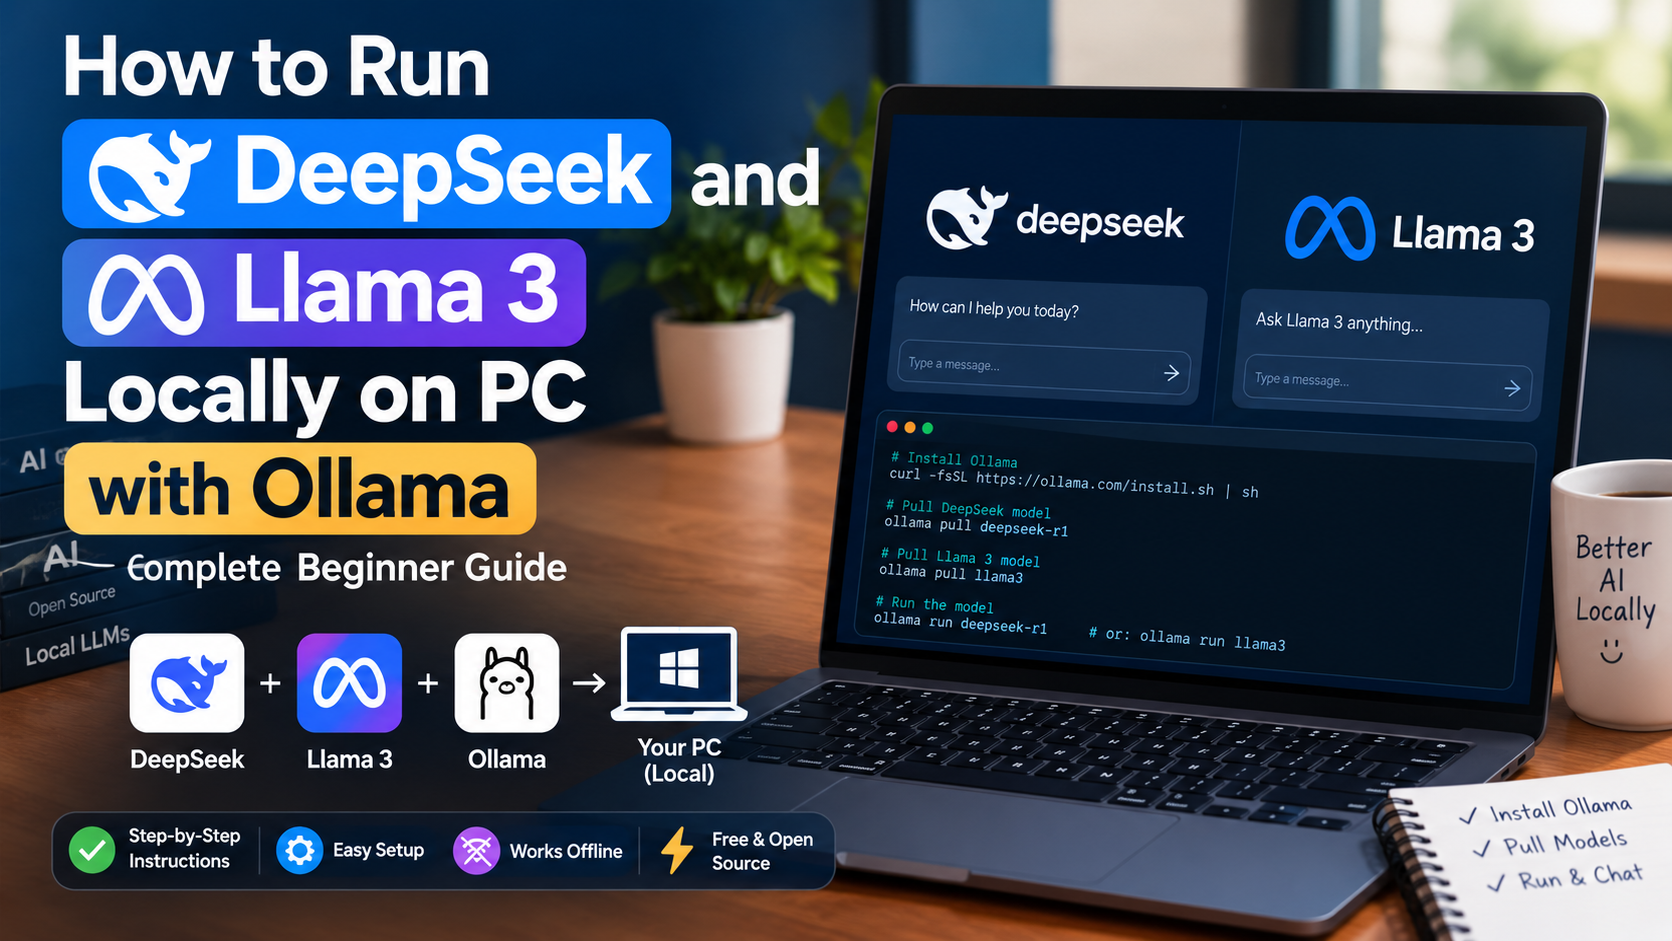
While cloud-based artificial intelligence services offer powerful remote compute clusters, relying on third-party APIs introduces significant trade-offs: ongoing monthly subscription fees, data privacy risks when handling confidential corporate files, rate limits, and service downtime during server outages. In 2026, learning how to run deepseek llama 3 locally ollama environment on your personal computer unlocks 100% data sovereignty, offline availability, and zero API token costs.
With lightweight open-source frameworks like Ollama, deploying frontier open-weights models (such as Meta’s Llama 3.3, DeepSeek-R1, DeepSeek-Coder, and Qwen 2.5) requires only a single terminal command. In this beginner-friendly tutorial, we cover system hardware requirements, VRAM allocation, step-by-step installation, running CLI chat interfaces, and attaching a modern ChatGPT-like browser GUI using Open WebUI. Once your local offline model is running, you can test prompt techniques from our prompt engineering guide 2026.
Why Run Open-Source AI Models Locally in 2026?
- 100% Absolute Data Privacy: Your prompts, source code, financial documents, and personal notes remain strictly inside your PC’s local RAM and storage. Zero telemetry or conversation logs are sent to external cloud servers.
- Zero Monthly Fees & API Token Costs: Eliminates recurring $20/month AI subscriptions or high pay-per-token API bills.
- Offline Independence: Run complex code autocomplete and document analysis in remote locations without requiring an active Wi-Fi or cellular internet connection.
- Custom Fine-Tuning & System Modelfiles: Define custom system prompts, temperature thresholds, and context window lengths directly via local configuration files.
Hardware VRAM & System RAM Requirements Matrix
Local LLM inference performance depends primarily on your computer’s dedicated GPU VRAM capacity or unified system memory. Open-source models are quantized into GGUF formats (such as 4-bit Q4_K_M) to compress parameter sizes while retaining over 95% of full-precision reasoning capabilities.
| Model Scale Class | Quantization Level | Minimum System VRAM / RAM | Recommended Open Models |
|---|---|---|---|
| Small (3B to 8B Parameters) | 4-bit (Q4_K_M) | 8GB System RAM or 6GB GPU VRAM | llama3.1:8b, deepseek-r1:8b, phi3:mini |
| Medium (14B to 33B Parameters) | 4-bit (Q4_K_M) | 16GB to 24GB Unified RAM / VRAM | qwen2.5:14b, deepseek-coder:33b, mistral:14b |
| Large (70B Parameters) | 4-bit (Q4_K_M) | 48GB GPU VRAM (or Apple M-Series 64GB) | llama3.3:70b, qwen2.5:72b, deepseek-r1:70b |
Step 1: Download and Install Ollama
Ollama simplifies local model management by acting as a background daemon that handles GPU memory allocation, token streaming, and REST API endpoints natively. To get started, visit the official Ollama official portal and download the free installer for Windows, macOS, or Linux.
Run the executable wizard and complete the default installation steps. Ollama will automatically register system environment variables and configure GPU acceleration drivers (NVIDIA CUDA, AMD ROCm, or Apple Metal).
Step 2: Pulling and Running Models in Terminal
Once installation finishes, open your PowerShell (Windows) or Terminal (macOS/Linux) to run deepseek llama 3 locally ollama commands directly. Execute the following line to pull and launch Meta’s Llama 3.1 model:
# Download and launch interactive terminal chat with Llama 3 (8B)
ollama run llama3.1
Ollama will stream the quantized model weights and launch an interactive prompt interface directly inside your terminal window. To run DeepSeek’s specialized reasoning models, execute:
# Download and launch DeepSeek-R1 reasoning model
ollama run deepseek-r1:8b

# Download DeepSeek Coder for software engineering tasks
ollama run deepseek-coder-v2
To view all active models stored locally on your hard drive, run:
ollama listStep 3: Installing Open WebUI for a ChatGPT-Style Graphical Interface
While terminal interaction works great for quick commands, most creators prefer a rich graphical user interface complete with conversation history, Markdown code rendering, file attachments, and model switching. The best open-source GUI for Ollama is Open WebUI.
If you have Docker Desktop installed on your machine, launch Open WebUI with this single command:
docker run -d -p 3000:8080 --add-host=host.docker.internal:host-gateway -v open-webui:/app/backend/data --name open-webui --restart always ghcr.io/open-webui/open-webui:mainOnce the container starts, open your web browser and navigate to http://localhost:3000. Create a local admin account, select your installed local model from the top dropdown, and enjoy a 100% private, offline AI workstation.
Step 4: Integrating Local Models into VS Code for Private Pair Programming
Software developers can leverage local Ollama instances directly inside Visual Studio Code for private inline code completion without sending proprietary client code to third-party APIs.
- Install Continue.dev Extension: Open the VS Code Extensions Marketplace and search for “Continue” (the leading open-source AI code assistant).
- Configure Provider: Open
.continue/config.jsoninside your home directory and set Ollama as your default provider. - Set Model Name: Point your autocomplete provider to
deepseek-coder-v2orllama3.1running on port 11434. - Enjoy Offline Coding: Highlight code blocks and press
Ctrl+I(orCmd+I) to refactor functions offline without latency delays.
Managing Local Modelfiles & Custom Instructions
You can customize how your local AI behaves by building custom Modelfiles. For example, to create a specialized Python coding assistant with strict system rules, create a text file named Modelfile:
FROM llama3.1
PARAMETER temperature 0.2
PARAMETER top_p 0.9
SYSTEM You are an expert Staff Python Engineer. Always output clean, PEP8 compliant code blocks without conversational filler.
Build your customized model binary by executing:
ollama create python-expert -f ./Modelfile
ollama run python-expert
Troubleshooting & Optimizing Performance
- Offloading Layers to GPU: If generation speeds feel slow, ensure your GPU drivers are updated. Ollama will automatically offload maximum transformer layers into GPU VRAM if sufficient capacity is available.
- Freeing System VRAM: To stop a running model and clear graphics VRAM, run
ollama stop llama3.1in your terminal. - Managing Disk Space: Large models require significant storage space (e.g., an 8B model takes ~4.7GB, while a 70B model takes ~40GB). Delete unused models using
ollama rm model-name.
Frequently Asked Questions (FAQs)
Q1: Does running models locally send any diagnostic data to external servers?
No. When you run deepseek llama 3 locally ollama scripts, all execution takes place 100% offline on your local CPU and GPU. No prompts, attachments, or conversation histories leave your machine.
Q2: Can I run local AI models on a laptop without a dedicated NVIDIA GPU?
Yes! Ollama runs efficiently on Apple Silicon Macs (M1/M2/M3/M4 chips) using unified memory acceleration. On standard Windows Intel/AMD laptops without dedicated GPUs, 8B models can run on system CPU RAM, though rendering speeds will be slower.
Q3: What is the difference between GGUF Q4, Q8, and FP16 models?
GGUF is a file format for local LLM storage. Q4 (4-bit quantization) uses minimal memory with high speed; Q8 (8-bit) offers higher precision with moderate VRAM usage; FP16 is uncompressed full precision requiring maximum VRAM.
Q4: Can local models analyze PDF documents and text files?
Yes! When using graphical interfaces like Open WebUI or AnythingLLM alongside Ollama, you can upload PDFs, text files, and spreadsheets to perform local retrieval-augmented generation (RAG) querying completely offline.
Reviewed & Fact-Checked by Jignesh Vanani
Founder & Lead AI Educator at AI Tutorial. All terminal commands, Docker WebUI deployments, and hardware VRAM benchmarks in this run deepseek llama 3 locally ollama guide were tested live in local workstation environments.